MULTIMODAL LEARNING  /  ADAPTIVE FINE-TUNING

MARS: Harmonizing Multimodal Convergence via Adaptive Rank Search

Choose the ranks that let vision and language learn in sync.

1University of Michigan    2NVIDIA

* Equal advising.

NeurIPS 2026
01Measuremodule dynamics
02Balanceconvergence time
03Selectthe best rank pair

30-SECOND OVERVIEW

MARS, in motion.

Abstract

Fine-tuning Multimodal Large Language Models (MLLMs) with parameter-efficient methods like Low-Rank Adaptation (LoRA) is crucial for task adaptation. However, imbalanced training dynamics across modalities often lead to suboptimal accuracy due to negative interference, a challenge typically addressed with inefficient heuristic methods such as manually tuning separate learning rates. To overcome this, we introduce MARS (Multimodal Adaptive Rank Search), an approach to discover optimal rank pairs that balance training dynamics while maximizing performance. Our key innovation, a proposed framework of dual scaling laws, enables this search: one law models module-specific convergence time to prune the search space to candidates with aligned dynamics, while the other predicts final task performance to select the optimal pair from the pruned set. By re-purposing the LoRA rank as a controller for modality-specific convergence speed, MARS outperforms baseline methods and provides a robust, automated strategy for optimizing MLLM fine-tuning.

Why is MARS needed?

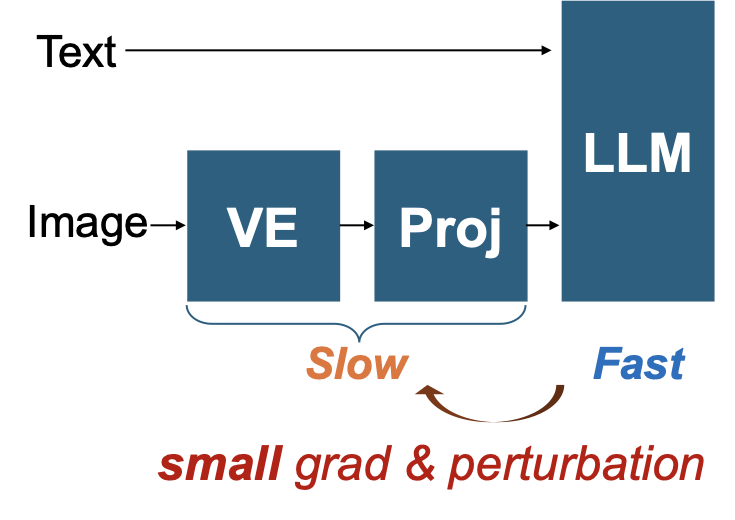
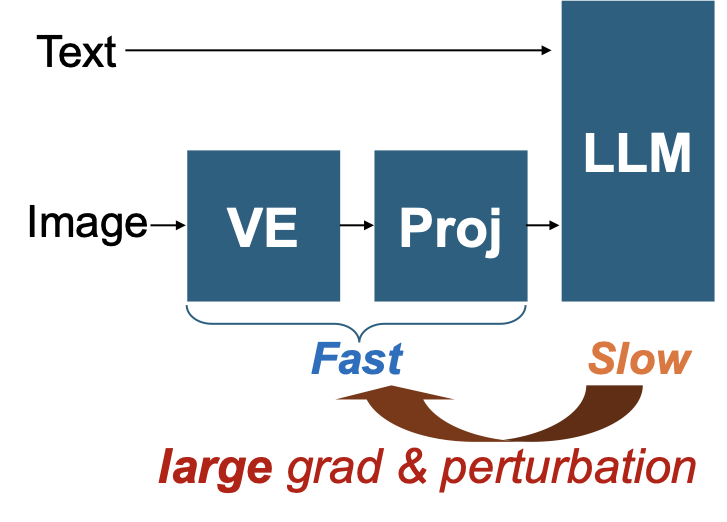
Imbalanced training dynamics between the Vision Encoder (VE) and LLM lead to suboptimal performance. When modules converge at different rates, it causes either performance bottlenecks or training oscillations.

VISION Vision Encoder visual adaptation
rve
balanced convergence
rllm
LANGUAGE LLM Backbone language adaptation

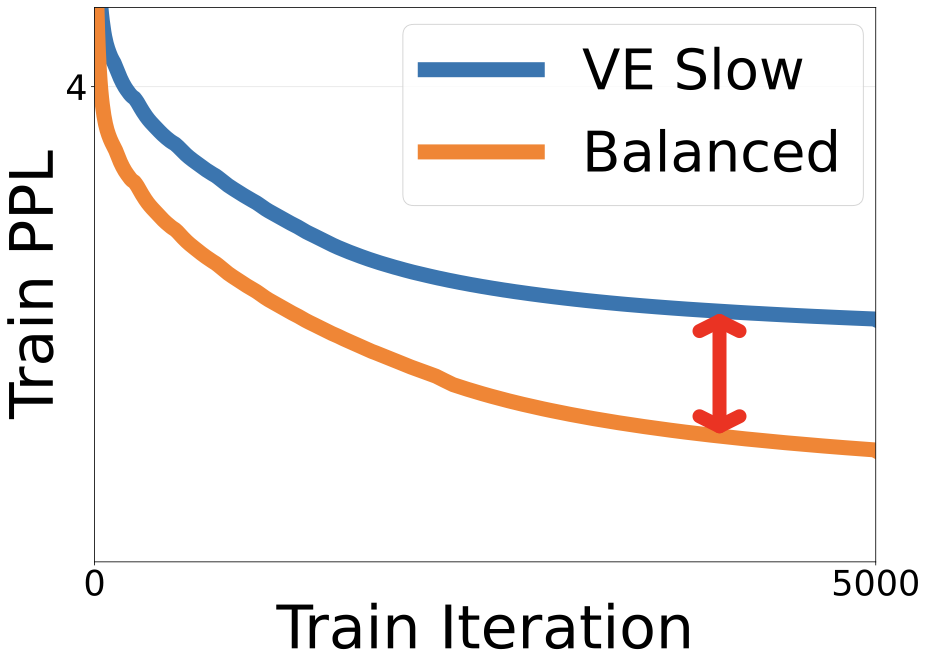
VE Slow Vision Encoder Under-adapted

VE Slow Diagram VE Slow Results

When the vision encoder is under-adapted (lrve ≪ lrllm), it creates a performance bottleneck that limits the overall model capability.

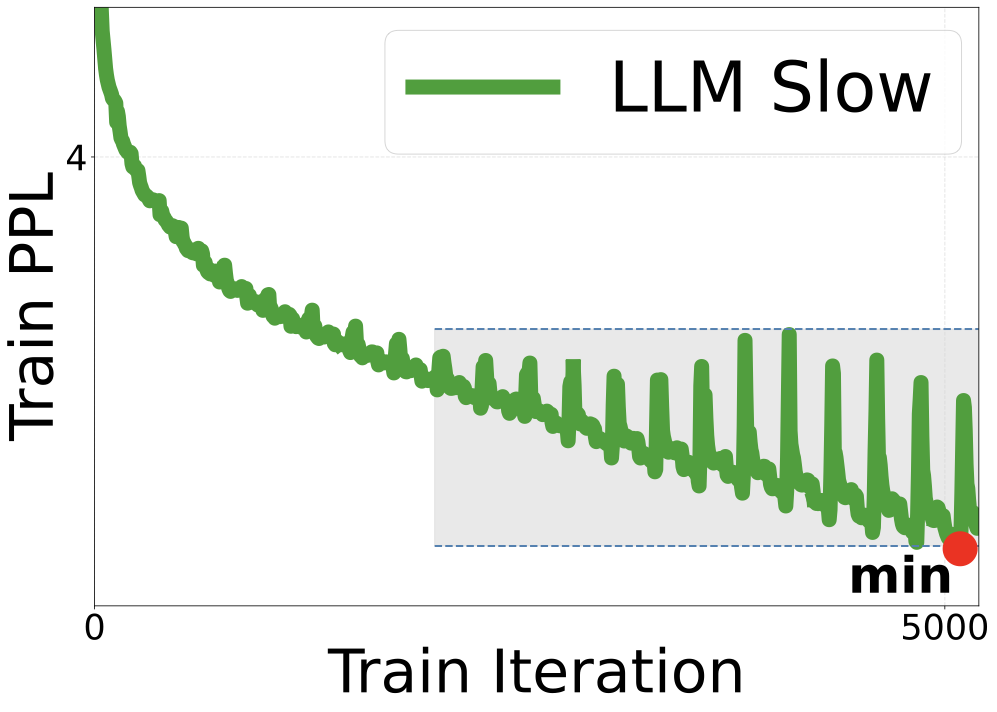
LLM Slow LLM Under-adapted
LLM Slow Diagram LLM Slow Results

When the LLM is under-adapted (lrllm ≪ lrve), it causes significant training instability and oscillations.

Balanced MARS Solution

MARS discovers optimal LoRA rank pairs that align convergence times (tve ≈ tllm), enabling stable training dynamics and maximum performance.
What MARS changes

1

Identifying the Core Problem

We identify and provide evidence that imbalanced training dynamics in MLLM fine-tuning, originating from a two-fold disparity (learning capacity and required learning budget), represent a key source of suboptimal performance.

2

Dual Scaling Laws Framework

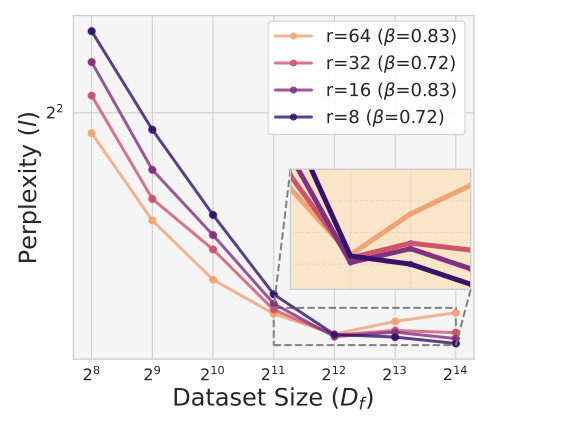
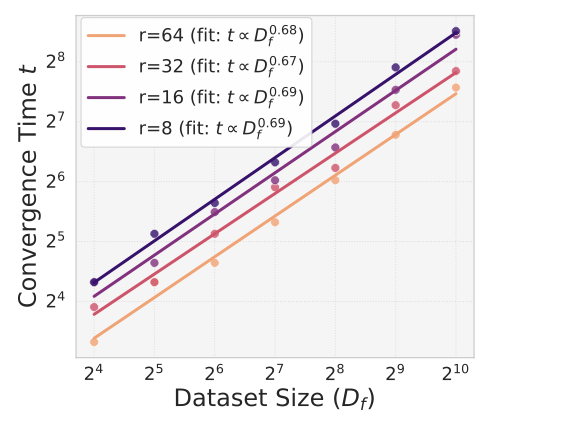
We are the first to propose and validate dual scaling laws for MLLM fine-tuning: Scaling Law-P (models performance) and Scaling Law-C (models module-specific convergence time), making the rank search feasible.

3

Superior Performance & Efficiency

MARS outperforms baselines with up to 12.0% higher ScienceQA accuracy and 13.2% lower LLaVA Bench perplexity, while demonstrating robust generality and an 11.5× reduction in total search and fine-tuning time.

Two laws. One rank pair.

MARS transforms the intractable search for optimal LoRA ranks into an efficient, guided procedure through a two-step process enabled by our dual scaling laws.

Dual Scaling Laws: The Predictive Foundation

Scaling Law-P

(a) Scaling Law-P: Performance as a function of dataset size for different LLM ranks.

Scaling Law-C

(b) Scaling Law-C: Convergence time as a function of dataset size for different LLM ranks.

Scaling Law-P (Performance)

p = A · 1/((rve)αm·(rllm)αl·Dfβ) + E

Predicts final task performance. Serves as the objective function to select the optimal rank pair from pruned candidates.

Key Findings
Performance is sensitive to VE-LLM rank interplay.
Optimal rank pair involves a trade-off with dataset size.

Scaling Law-C (Convergence)

ti = ki · (ri)γi · Dfδi + Ei

Models convergence time for each module. Used to prune the search space to candidates with aligned dynamics (tve ≈ tllm).

Key Findings
Increasing dataset size increases convergence time.
Increasing rank size decreases convergence time.

Two-Step Search Process

1

Pruning via Convergence Balancing

MARS uses Scaling Law-C to enforce a balance condition (tve ≈ tllm). This drastically prunes the search space to candidate pairs predicted to exhibit stable, harmonized training dynamics.

2

Selection via Performance Prediction

From the pruned set of stable candidates, MARS uses Scaling Law-P to predict the final task accuracy for each pair and selects the one with the best predicted outcome.

Results

+12.0%
Higher Accuracy
ScienceQA Benchmark
-13.2%
Lower Perplexity
LLaVA Bench
11.5×
Faster Search
vs Naive Search

APPENDIX I / GENERALITY

One rank pair, broader capabilities.

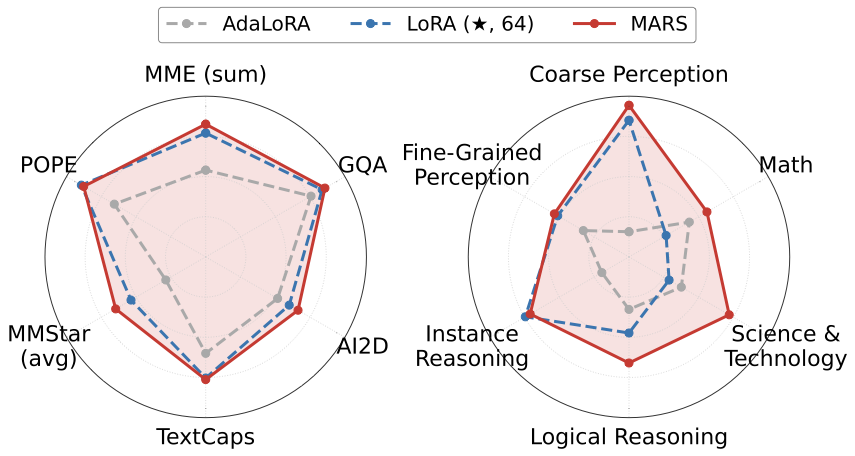
MARS is evaluated across six multimodal benchmarks and six MMStar capability groups.

HOW TO READ THE PLOTS Farther outward means better.

Each axis uses a lightly padded comparison range so differences remain visible without touching the center or edge. Select a method below to show or hide it; hover a point for its exact Appendix I value.

Loading interactive benchmark plots…

Comparison with Fixed-Rank Tuning (Different Learning Rates)

Model Benchmark LoRA (⋆, 1e-5) LoRA (⋆, 1e-6) LoRA (⋆, 1e-7) MARS
LLaVA-OV-0.5B LLaVA (↓) 2.7336 2.771 2.8472 2.7188
ScienceQA (↑) 71.06 61.88 59.28 72.85
LLaVA-OV-7B LLaVA (↓) 2.2317 2.295 2.4346 2.1875
ScienceQA (↑) 72.26 69.86 67.27 74.25
Qwen2.5-VL-3B LLaVA (↓) 3.6156 3.7415 4.1557 3.5925
ScienceQA (↑) 78.04 76.45 76.25 79.24
Qwen2.5-VL-7B LLaVA (↓) 3.5032 3.5908 3.8716 3.3879
ScienceQA (↑) 79.84 76.25 74.25 79.64

Comparison with Adaptive Rank Search Baselines

Model AdaLoRA GeoLoRA Full-rank LoRA (⋆, 16) LoRA (⋆, 32) MARS
LLaVA Bench (perplexity ↓)
LLaVA-OV-0.5B 2.8973 2.8801 2.7209 2.7336 2.7331 2.7188
LLaVA-OV-7B 2.5189 2.4888 2.2693 2.2317 2.4420 2.1875
ScienceQA (accuracy % ↑)
LLaVA-OV-0.5B 62.28 63.52 69.66 71.06 69.86 72.85
LLaVA-OV-7B 66.27 67.81 70.46 72.26 73.65 74.25

BibTeX

@inproceedings{cho2026mars,
    title={MARS: Harmonizing Multimodal Convergence via Adaptive Rank Search},
    author={Cho, Minkyoung and Jang, Insu and Jin, Shuowei and Zhao, Zesen and Jothi, Adityan and Can, Ethem F. and Chen, Min-Hung and Mao, Z. Morley},
    booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
    year={2026}
}